Evals
Evals let you systematically test how well Supersimple's AI follows your intended logic and rules.
Build a suite of questions (cases), each with one or more checks written in plain language. An AI judge grades the answers against your checks, such as whether the AI used the right metric and model, applied a specific filter, or excluded certain records.
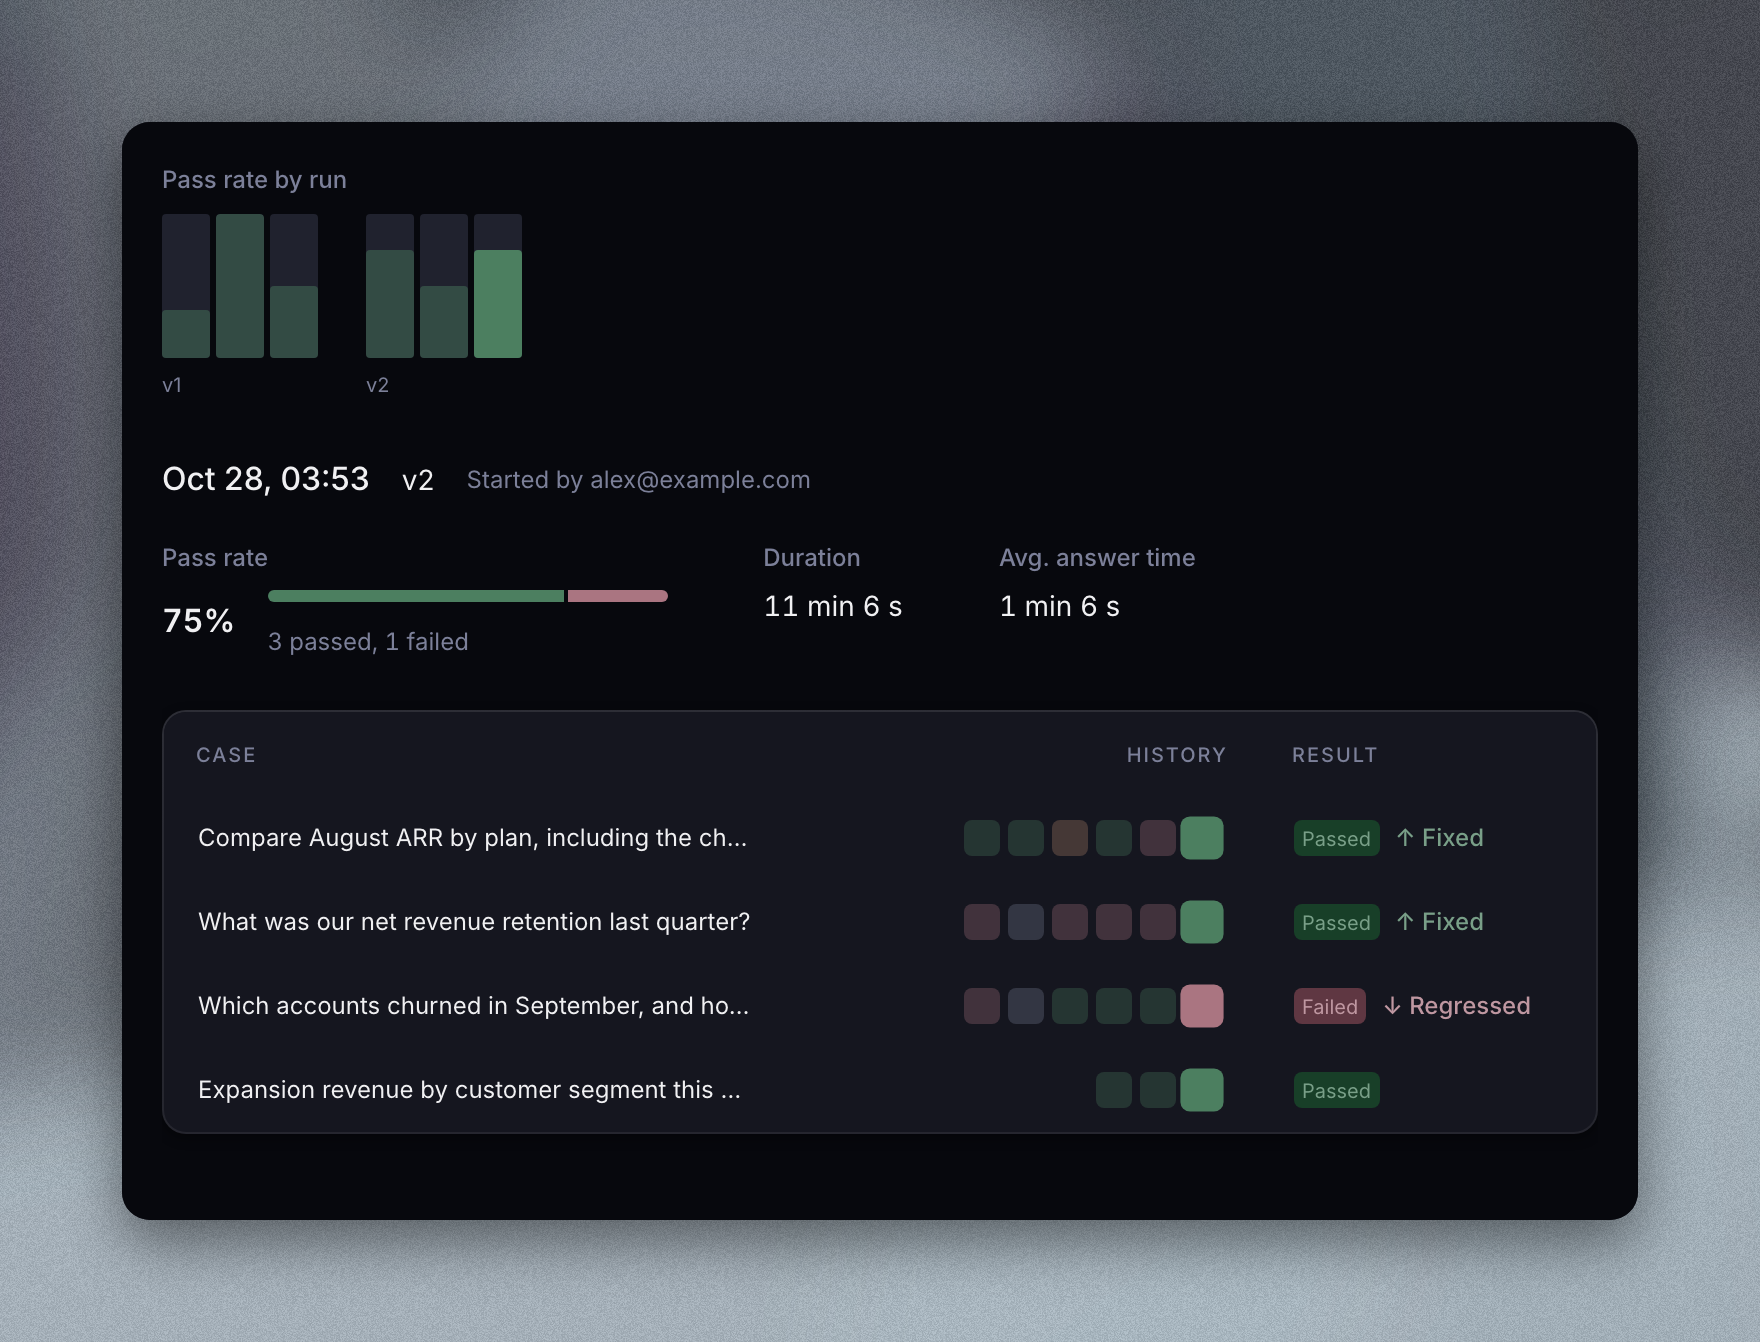
Author suites as YAML and run them from the UI or CLI, including in CI. Our updated AI coding agent skill also helps your coding agent write and run evals.
See the Evals docs to get started.